


Welcome to Issue 4 of the China AI Bulletin, the latest on AI development, governance, and safety in China. Today’s highlights: CAC launches a four-month enforcement campaign taking on AI “digital slop,” three agencies jointly release a tiered governance for AI agents, and Trump and Xi commit in principle to a second intergovernmental AI dialogue at the May 19 summit.
Number of the week: 608—the number of new deep synthesis service algorithms filed in the latest disclosure
Executive Summary
Domestic AI Governance: CAC launched a four-month AI enforcement campaign covering fourteen categories, including open-source model accountability and AI “digital slop.” CAC, NDRC, and MIIT jointly issued the Implementation Opinions on Intelligent Agents, outlining a tiered governance framework across nineteen priority sectors. Both 2026 national legislative work plans mention a comprehensive AI law, but not as a top priority.
National Standards: TC260-005 on ethics & safety guidelines mentioned application-level loss-of-control and off-switch obligations. TC28/SC42 increased its focus on trustworthiness with a set of new standards. AI safety WG9 advanced the Intelligent Agent Application Security Basic Requirements to formal deliberation as a rare mandatory national standard. SAC’s GB/Z 177 introduced AI Terminal Intelligence Grading, and CAC stood up an AI-cybersecurity testing programme with Huawei as the technical support unit.
International AI Governance: Following Trump’s Beijing visit, the two governments reportedly agreed to launch a bilateral intergovernmental AI dialogue. Treasury Secretary Bessent informally surfaced the agreement on May 14 and MFA spokesperson Guo Jiakun announced it May 19, but the US has not officially confirmed.
Notable Model Releases: Alibaba launched Qwen 3.7-Max claiming 35-hour autonomous operation, paired with its new Zhenwu M890 custom AI chip. Tencent compressed HY-MT1.5-1.8B into 1.25-bit and 2-bit quantized variants for mobile devices, and released Hy-Embodied-RoboFusion and R-DMesh for embodied AI research and 3D animation.
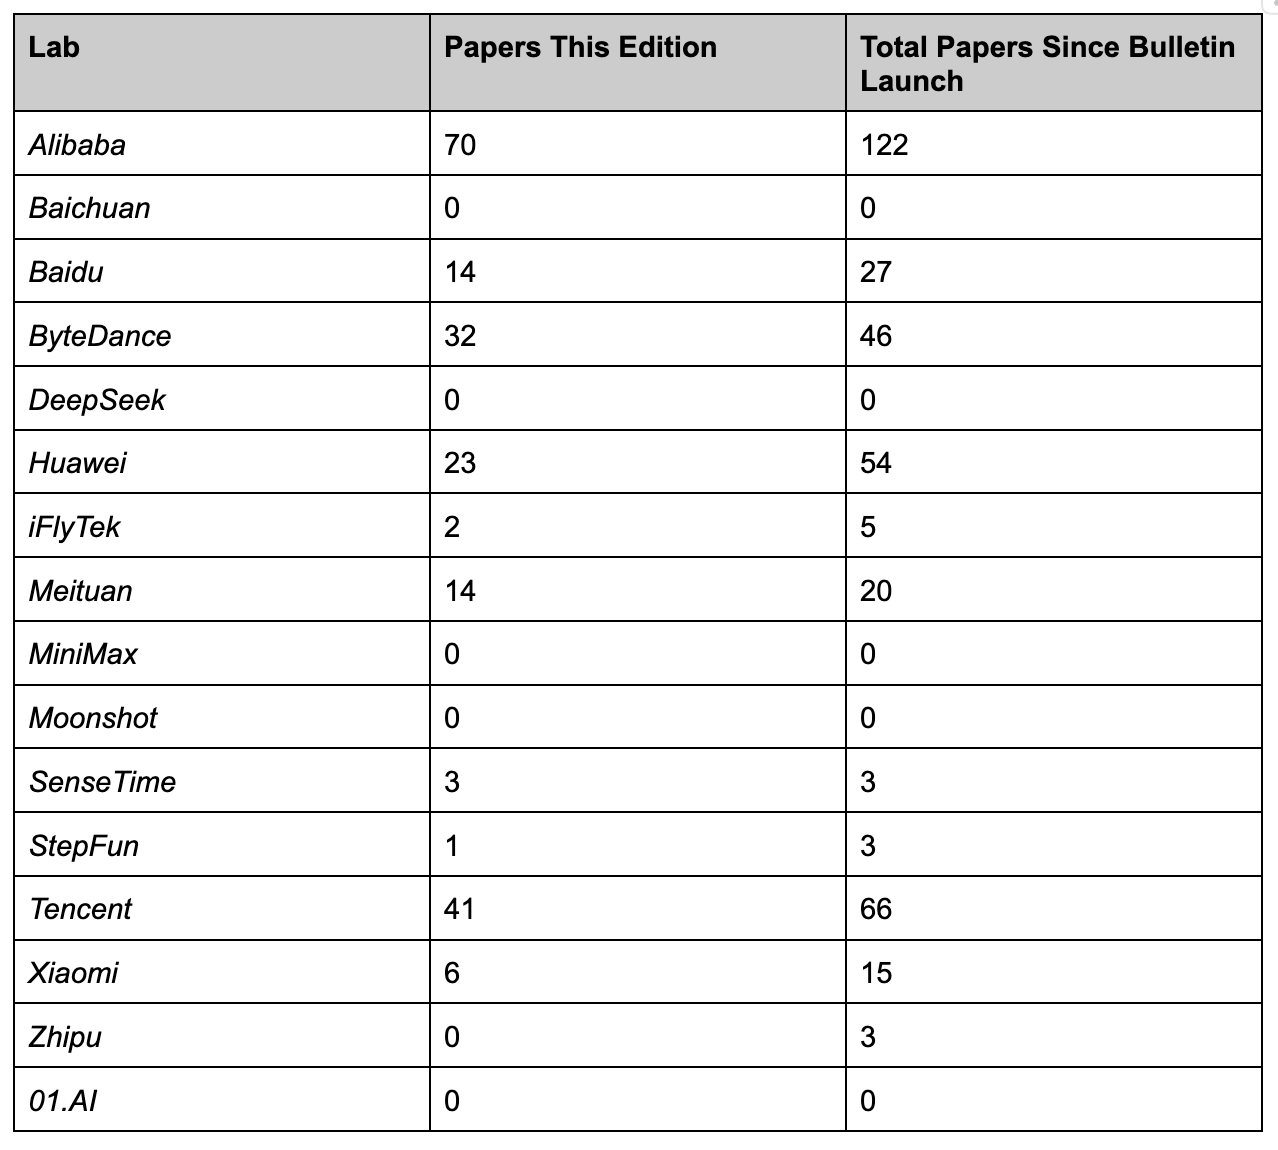
Technical Papers: Frontier labs released 206 papers, led by Alibaba (70), Tencent (41), and ByteDance (32). Highlights: Alibaba’s Qwen-Scope open-source SAE suite for interpretability, ByteDance’s A-CODE (atomic-level protein design), and Tencent’s CL-bench Life real-life context benchmark (frontier models score 19.3%).
Technical AI Safety: 172 safety papers were released this edition. Shanghai AI Lab released several focused on agentic safety, and Tencent’s Safe, or Simply Incapable? discusses phone-use-agent safety evals.
Domestic AI Governance
CAC targets AI “chaos” in enforcement sweep
On April 30, the Cyberspace Administration of China deployed a four-month Qinglang special action on AI application chaos (清朗·整治AI应用乱象). Qinglang (清朗, “clear and bright”) is CAC’s umbrella brand for online-content enforcement campaigns, launched in 2016 and running regularly since 2020. They cover issues like livestream regulation, algorithm abuse, and the protection of minors. This is the second AI-specific Qinglang campaign after the May 2025 “AI technology abuse” action, but where the 2025 version focused on content misuse, the 2026 edition expands enforcement to the entire AI service lifecycle and runs in two phases. Phase one targets seven categories at the infrastructure layer: genAI services running without filing under the 2023 Generative AI Services Interim Measures, insufficient safety guardrails and review capabilities, unauthorized or low-quality training datasets, AI data poisoning (including malicious generative-engine optimization and an e-commerce trade in poisoning tools), non-compliance with the AI-Generated Content Labeling Methods, AI-enabled cyberattacks and unauthorized face-swap/voice-clone services, and open-source model safety management. Phase two adds seven content-layer categories: AI “remixing” of classics into 数字泔水 (”digital slop”), false information including impersonation of party and state media, deepfake imagery of public figures and “AI resurrection of the deceased,” violent or vulgar generation, harm to minors, AI-driven trolling, and non-compliant AI products and shell apps.
The digital-slop framing is already rippling through state media. A May 17 Science & Technology Daily commentary1 connects two Phase 2 categories, digital slop and harm to minors, by arguing that “AI垃圾视频” (AI garbage videos) are reshaping cognitive development in young children whose brains are still building basic models of how the physical world works. The piece cites 278 identified channels generating such content, with 63 billion accumulated views and 220 million subscriptions.
Per the Beijing Academy of AI (BAAI)’s AI Governance Weekly, filing registration, training-corpus compliance, AI data poisoning, and open-source model safety management are all new in the 2026 campaign relative to 2025. The open-source provision is the most consequential of the four: it applies the content-platform accountability regime (identity verification, dataset and model takedowns, and emergency-response mechanisms) to open-source AI hosts, treating them as content platforms rather than as developer infrastructure.
Joint framework for agentic AI released
On May 8, CAC, the National Development and Reform Commission (NDRC), and the Ministry of Industry and Information Technology (MIIT) jointly issued the Implementation Opinions on Standardized Application and Innovative Development of Intelligent Agents.2 The document is framed as an implementation of the AI+ Action Plan and foregrounds the need for agent safety and controllability3 (reiterated in a Xinhua Q&A) as well as innovation and application-driven development.4 It’s structured around four pillars: strengthening the development foundation5 through technical development and standards; holding the safety bottom line6 by improving standards, safety/security measures, governance, and self-regulation; driving application uptake7 by supporting research, development, and applications while promoting well-being and social governance; and building an innovation ecosystem8 by promoting industrial cooperation and promoting new agent applications. One of the governance measures it calls for is a tiered agent governance framework (Article 11), which subjects sensitive sectors and key industries to mandatory filing, testing, and problem-product recall, potentially paired with the voluntary “agent registry platform”9 proposed in Article 4 of the same document, which would provide digital identity management, discovery, and capability declarations for agents. This builds on a registry concept the bulletin previously tracked in the National Information Security Standardization Technical Committee (TC260)’s OpenClaw-type Agent Practice Guide (March 31), which called for enterprise-level asset registries of approved agent deployments; Article 4 lifts the concept from organizational to national scope.
CAC paired the release with five same-day expert interpretation pieces by Chinese Academy of Engineering (CAE) academician Wu Hequan, China Academy of Information and Communications Technology (CAICT) president Yu Xiaohui, MIIT-sector science-and-technology ethics committee chair Wei Yiming, China Center for Information Industry Development (CCID) AI research director Zhong Xinlong, and Tsinghua’s Xue Lan. Zhong Xinlong opens with the most explicit safety framing, citing the wide deployment of OpenClaw since the start of 2026 as having “exposed risk hazards including agents’ ability to launch network attacks under instruction inducement,”10 and names medical, transportation, and public safety as sectors warranting mandatory standards. Xue Lan frames the document as a governance shift from content risk to behavioral risk; content-safety measures, which much existing genAI regulation focuses on, can no longer cover the threat surface once AI takes autonomous actions, and the new risk categories he names are excessive permissions, behavioral loss-of-control, and tool poisoning. Yu Xiaohui makes the parallel technical case: traditional perimeter defense models face failure against agents’ multi-modal autonomous decision-making, so embedded rules and behavioral guardrails must replace boundary-based security. Wei Yiming calls behavioral control the new safety boundary and proposes blockchain-based verifiable and traceable mechanisms in important application scenarios; Wu Hequan explains why agent risk is qualitatively different around autonomy, coordination, and plasticity.
MIIT launches ten-province ethics-review pilot
On May 9, MIIT issued a notice launching a six-month pilot program to implement the Interim Measures for the Ethical Review and Service of Artificial Intelligence Science and Technology Activities, a framework MIIT issued jointly with nine other agencies. The pilot covers ten provinces and municipalities (Beijing, Shanghai, Guangdong, Shandong, Tianjin, Sichuan, Jiangsu, Hubei, Hunan, and Zhejiang) and runs June 1 through November 30. By the close of the period, MIIT expects participating regions to have connected ministerial, provincial, and municipal review chains, built an AI ethics risk case database, formulated five or more standards, and trained dedicated review personnel and institutions.
Coverage is structured around a mandatory base layer plus sectoral choice to align with “local realities.”11 Every participating city must conduct ethics review on AI’s foundational layer of data, algorithms, and models, and select at least three vertical application domains from a list of nine: manufacturing, education, science and technology, culture, healthcare, finance, agriculture, tourism, and consumer. The pilot can be seen as an operational link between the new TC260 AI Application Ethics & Safety Guidelines 1.0 instruction that developers “meet our country’s AI science-and-technology ethics review requirements” (see analysis below) and what those requirements look like in practice.
Both legislative work plans include an AI Law, but not as top priority
On May 11, the State Council and the NPC Standing Committee both published their respective 2026 annual legislative work plans. The State Council plan calls for “accelerat[ing] comprehensive AI legislation”12 and names six key legislative elements (data, compute, algorithms, IP, cybersecurity, and supply chain security); this signals that activity on AI laws and regulations is likely to keep accelerating across these domains, even as the plan does not restore the comprehensive AI Law itself to the preparatory-item status it held in 2023 and 2024—the 2025 plan dropped it entirely, replacing it with generic language about “advancing legislation for the sound development of AI.” The NPC Standing Committee plan lists AI only as a backup research topic, the lowest of three legislative priority tiers, grouping “the healthy development of artificial intelligence” with fiscal policy, agricultural support, and online violence governance as subjects warranting study rather than active drafting. The 2025 NPC SC plan had directed that AI legislation “shall be researched and drafted promptly by relevant departments, and deliberation shall be arranged as appropriate”—a research-and-drafting status the 2026 plan downshifts to research only. The combined picture is two-track: regulatory activity across the six named elements is likely to keep accelerating, but the timeline for a singular comprehensive AI Law is likely longer.
National Standards
TC260 releases ethics & safety guidelines for AI applications
On May 19, TC260 released TC260-005 《人工智能应用伦理安全指引 1.0》 (AI Application Ethics and Safety Guidelines 1.0). The document is a TC260 technical reference document, characterized as “principle-based and reference-only,”13 and is intended to coordinate with existing rules on personal information, automated decision-making, content labeling, algorithmic governance, and intellectual property (IP) rather than to add binding obligations.
The document is substantially concerned with loss of control, but at the application level rather than the model level. The first of six ethics-safety impact categories is “human dominance impact,”14 defined as AI behavior exceeding “preset, understood, and controllable range” (Section 4). Ultimate authority over AI must belong to humans, and AI must always remain under human control to “prevent AI from escaping human oversight or threatening human survival and development”15 (Section 5.2(g)). Developers building “highly autonomous AI applications” must “focus on assessing loss-of-control risk and its impact on industry and society”16 (Section 6.2(b)). This vocabulary was introduced into Chinese standards-track text by TC260’s AI Safety Governance Framework 2.0 (September 2025), which named “trustworthy application, preventing loss of control”17 as a foundational governance principle. TC260-005 carries the same framing forward into a developer obligation for highly autonomous AI applications. It also recommends an “off switch” that users can use to shut down a service (Section 6.3(d)).
The document also comments on open-source development and security, encouraging the open-sourcing of AI models, tool components, and evaluation benchmarks alongside open-source ecosystem-security capacity (Section 5.2(i)), complementing rather than contradicting Qinglang’s open-source accountability provisions above. The document functions as guidance, not binding rule, and the 1.0 versioning signals further iterations planned.
TC28/SC42 publishes foundational AI trustworthiness standard
On April 30, the Standardization Administration of China (SAC) Announcement No. 21/2026 approved GB/T 47507-2026 《人工智能 可信赖 通则》 (Artificial Intelligence — Trustworthiness — General Rules), set to be implemented August 1, 2026. The standard was drafted under TC28/SC42, the AI subcommittee of the National Information Technology Standardization Technical Committee, by 40 organizations and 87 named individuals over a 21-month cycle that began in March 2024. The roster centers on the China Electronics Standardization Institute (CESI), the Chinese Academy of Sciences (CAS) Institute of Software, and the Nanjing Software Technology Research Institute, joined by SenseTime, Ant Group, Baidu, Hikvision, Tencent Cloud, CloudWalk, Inspur, and the Shanghai AI Innovation Center, with universities including Beihang, Xi’an Jiaotong, and Shandong. None of the TC260-005 drafters (Tsinghua, I-AIIG, Alibaba, Huawei, and DeepSeek) appear on this roster.
GB/T 47507 anchors a growing TC28/SC42 trustworthiness family. The published record cross-references six related plans, four already published. Companion standards under TC28/SC42 include Trustworthy Datasets, General Requirements of Trustworthiness for Embodied Intelligence, and Generative AI System Risk Response Guide.
WG9 holds second 2026 plenary; agent-security standard enters deliberation
On May 12–13, the AI Safety Standards Working Group (WG9) under TC260 held its second 2026 plenary in Shanghai, drawing more than 350 representatives from over 200 organizations. Zhou Bowen (周伯文), director of Shanghai AI Lab and head of the committee, chaired the meeting. The plenary reviewed 16 national cybersecurity standard projects spanning edge-side LLMs, deepfake/synthesis security, embodied AI, testing-agency capabilities, foundation-model safety, model development and open-source safety, training and inference frameworks, system interoperability, and seven sectoral guidance documents (broadcasting, education, finance, healthcare, emergency management, and government affairs).
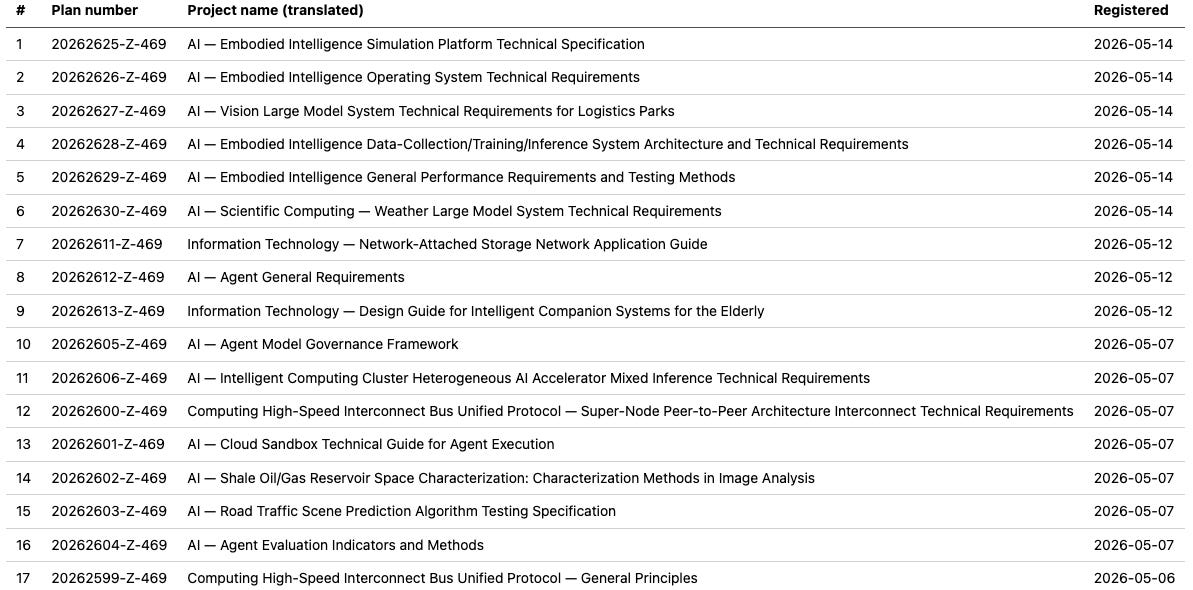
Two items were deliberated: the AI Safety Standards System18 and the Intelligent Agent Application Security Basic Requirements,19 the latter drafted as a mandatory national standard (GB) rather than a recommended one (GB/T). Mandatory-tier AI standards are relatively unusual in China; the agent-security standard’s development overlaps the same window as the May 8 Implementation Opinions on Intelligent Agents (CAC/NDRC/MIIT), reflecting attention to agent security from China’s standards track and policy-direction track in the same cycle. The standard also runs alongside TC28/SC42’s plan 20262612-Z-469 (AI — Agent General Requirements), the technical guidance document in the TC28/SC42 reference table below. China’s two principal AI standards bodies are now drafting parallel agent-security standards at different binding tiers.
AI terminal intelligence grading series released
On April 30, SAC Announcement No. 19/2026 approved the GB/Z 177-2026 series 《人工智能终端智能化分级》 (Grading the Intelligence Levels of AI Terminals), publicly announced by MIIT on May 8 as a joint release with the Ministry of Commerce (MOFCOM) and the State Administration for Market Regulation (SAMR). GB/Z 177.1 (Reference Framework) and GB/Z 177.2 (General Requirements) define what counts as “intelligence” in an AI terminal, the grading scale, and testing methods; GB/Z 177.3, 177.4, 177.7, 177.8, and 177.9 cover specific product categories (Mobile Terminals, Microcomputers, Automotive Cockpit, Speakers, and Earphones). Based on the MIIT announcement, 177.5 and 177.6 are likely Televisions and Smart Glasses, but only the five appear in the SAC release.
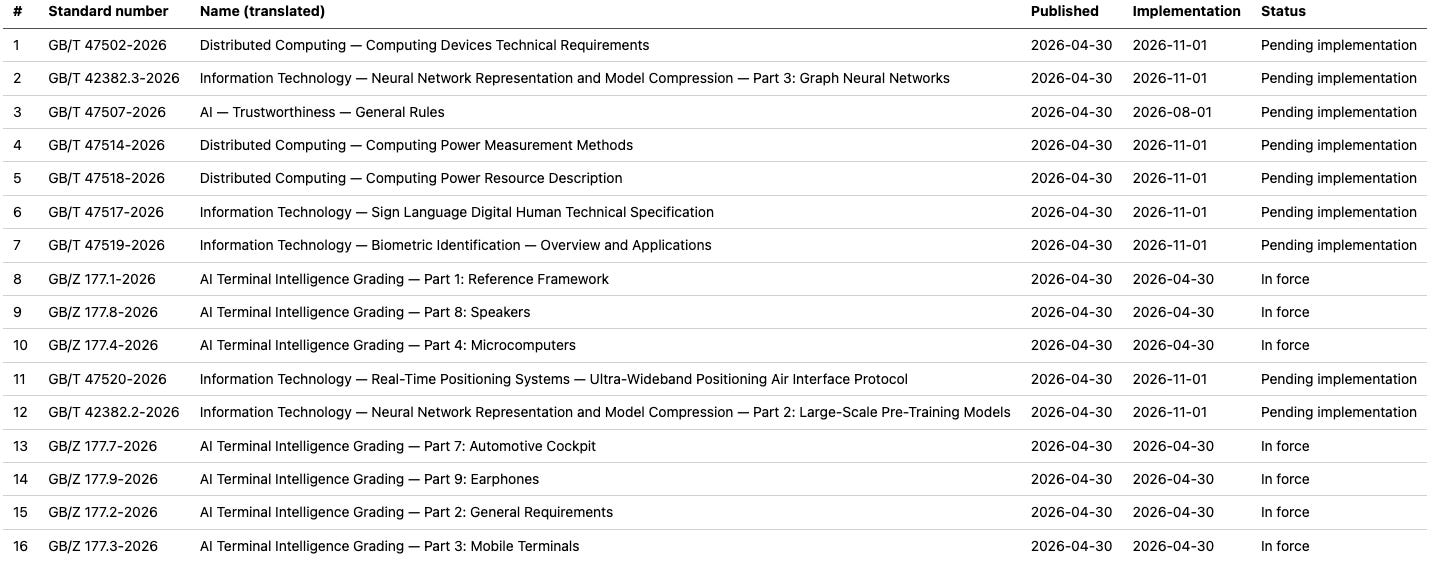
TC28/SC42 also registered a batch of new technical guidance documents, laid out in the table below.
CAC stands up AI-cybersecurity testing programme supported by Huawei
On May 18, CAC announced the 2026 Test on the Application of Artificial Intelligence Technology in Cybersecurity, a competition that runs from June till August, with results showcased at the National Cybersecurity Promotion Week in September. CAC’s Network Security Coordination Bureau and 15 other ministries and central bodies act as guiding units. The National Computer Network Emergency Response Technical Team (CNCERT) hosts, and Huawei is named as the sole Technical Support Unit.
Though unclear if concerns about Anthropic’s Mythos played a role, the eight designated scenarios mix conventional cybersecurity applications (network defense, vulnerability discovery, and network traffic threat detection) with items oriented toward frontier AI safety, like large model safety guardrail testing and AI agent malicious operation behavior detection.
Other news: AI+ Energy & leader inspections
On the same day as the Intelligent Agents Implementation Opinions were released, NDRC, the National Energy Administration, MIIT, and the National Data Bureau jointly issued the Action Plan on Promoting Mutual Empowerment between AI and Energy, outlining 29 tasks across two pillars: energy supporting AI compute and AI supporting energy applications.
Three high-level AI inspections occurred in nine days. NDRC Chair Zheng Shanjie visited Shanghai AI Lab on May 9, and on May 18 Premier Li Qiang inspected AI-manufacturing integration in Beijing and Vice Premier Ding Xuexiang inspected national integrated compute network construction.
International AI Governance
US and China agree to launch government-to-government AI dialogue at Trump-Xi summit
Following Trump’s early-May visit to Beijing, the two governments agreed to a bilateral AI dialogue—the second formal intergovernmental dialogue on AI between the two countries, after a prior round in May 2024. Treasury Secretary Scott Bessent first informally alluded to the agreement on May 14; Chinese Foreign Ministry spokesperson Guo Jiakun confirmed it at the May 19 regular press briefing. The Chinese readout states that “during President Trump’s visit to China, the two heads of state held constructive exchanges on AI issues and agreed to launch a government-to-government AI dialogue,”20 but the US has not officially confirmed.
Frontier Lab Developments
Notable Model Releases
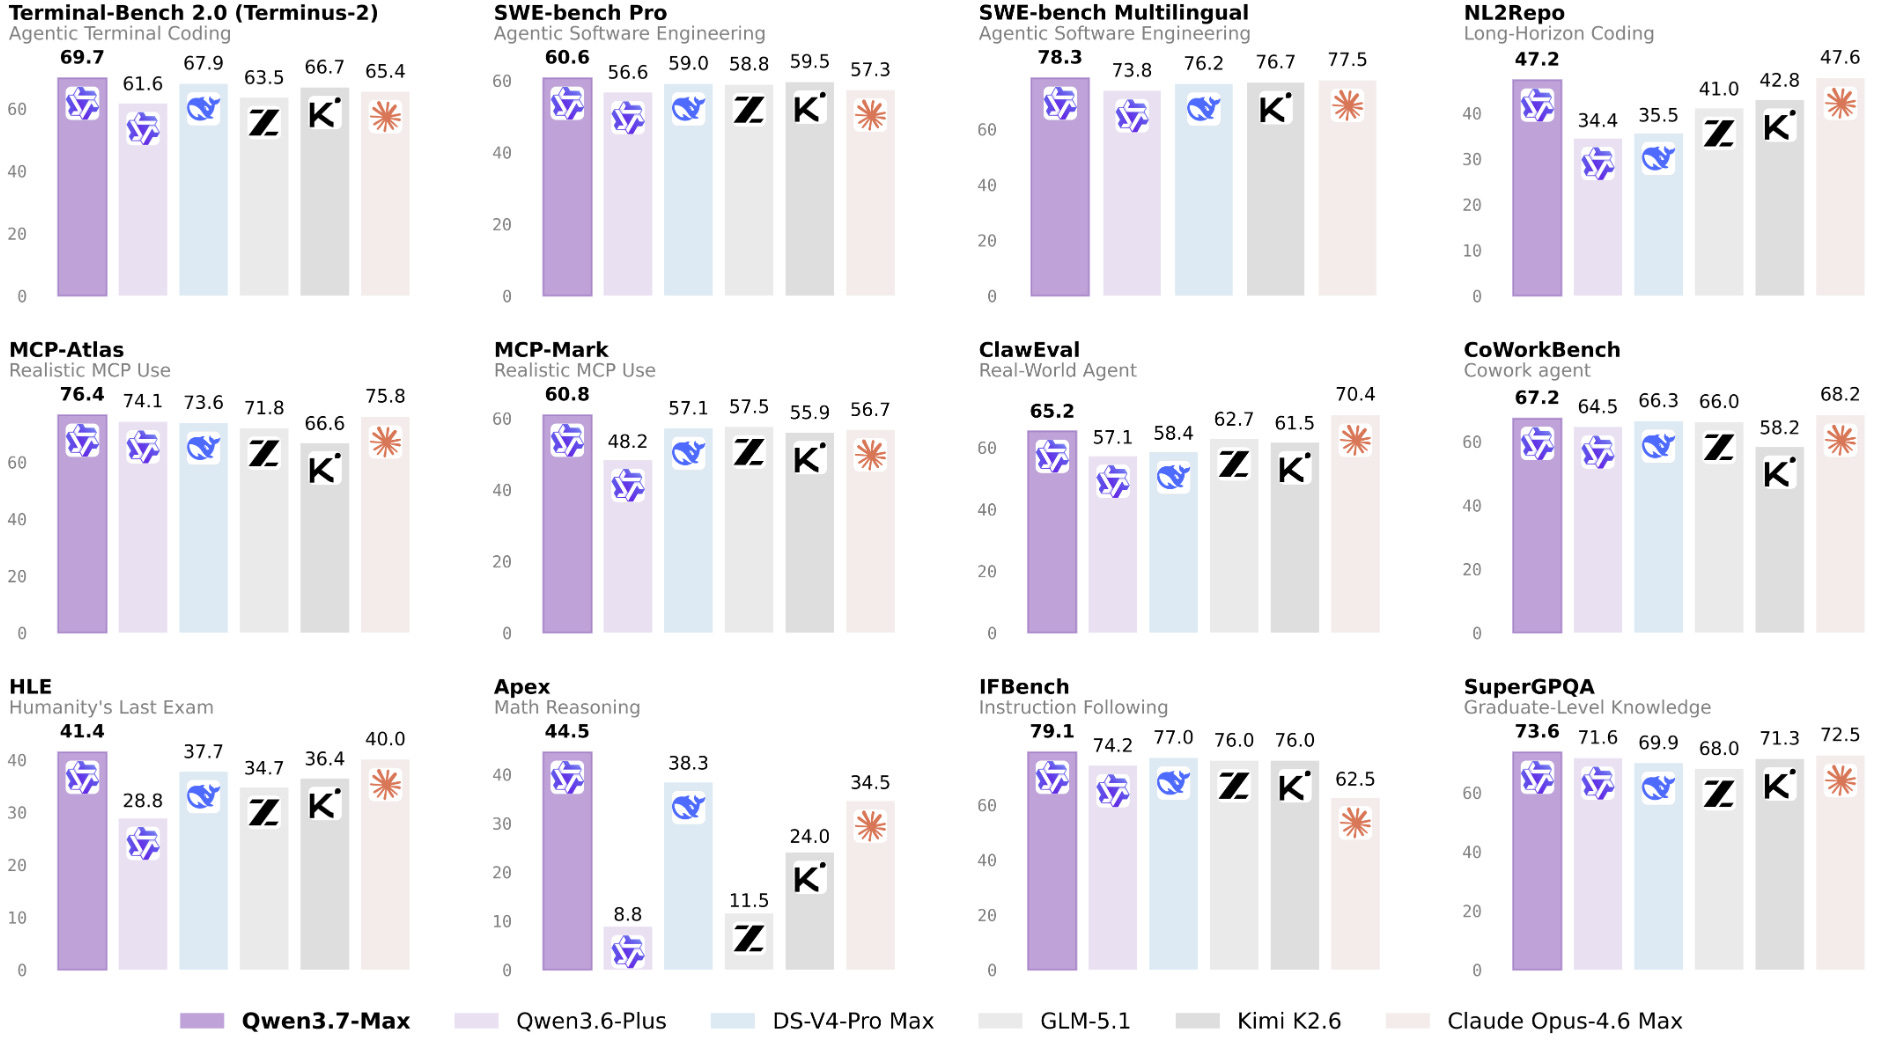
Alibaba launched Qwen 3.7-Max as “a proprietary model designed for the agent era.” The model targets agentic coding, complex reasoning, and extended multi-step tasks, with claimed autonomous operation up to 35 hours and over 1,000 tool calls without performance degradation. Two previews had surfaced on LMArena five days earlier: Qwen3.7-Max-Preview ranked 13th globally on the text leaderboard, and Qwen3.7-Plus-Preview ranked 16th globally on the vision leaderboard. The launch came paired with Alibaba’s new Zhenwu M890 custom AI chip. Alibaba Cloud senior vice-president Liu Weiguang framed the company’s positioning as “China’s AI factory,” claiming Alibaba is the only Chinese company operating all five layers of the full AI stack: chips, agentic cloud, AI models, model service platforms, and agentic applications.
Baidu released ERNIE 5.1 Preview on April 30 and the official ERNIE 5.1 as a closed model on May 9. The model is text-only and built on Mixture-of-Experts (MoE), focused on efficiency with roughly one-third of ERNIE 5.0’s total parameters and half its active parameters. Baidu claims a pre-training cost of about 6% of comparable models. ERNIE 5.1 ranks fourth globally on LMArena Search and first among Chinese models with a score of 1,223. Reported benchmark numbers include 99.6 on AIME26 with tools, τ³-bench and SpreadsheetBench-Verified scores surpassing DeepSeek-V4-Pro, and creative-writing performance approaching Gemini 3.1 Pro. The efficiency-first framing runs in contrast to the trillion-plus flagship models covered in Issue 3.
ByteDance released Lance on May 15 (technical paper), a 3B-parameter native unified multimodal model spanning six tasks across two modalities: text-to-image, image understanding (visual question answering, reasoning), image editing, text-to-video, video understanding, and video editing. Total training budget was 128 A100 GPUs, more efficient than what comparable unified multimodal models typically require. Lance claims competitive scores on a variety of benchmarks against far larger models. The efficiency-at-3B framing positions Lance as a contrast to the scale-driven flagships covered in Issue 3.
Tencent compressed HY-MT1.5-1.8B into 1.25-bit and 2-bit quantized variants (April 29) using Stretched Elastic Quantization (SEQ); the compressed versions target mobile devices. Tencent also released Hy-Embodied-RoboFusion (May 6) for embodied AI research and R-DMesh (May 13), a video-guided 4D mesh animation framework from the same team.
Technical Publication Highlights
It was a big few weeks of publishing: frontier labs released 206 papers on arXiv this edition. Alibaba authors led the pack with 70, and SenseTime put itself on the board. Highlights are below; a full list with summaries can be found here.
Alibaba
Venus-DeFakerOne: Unified Fake Image Detection & Localization
DeFakerOne unifies fake image detection and localization across deepfakes, AI-generated content, and document forgeries by combining vision-language and segmentation models. It outperforms baselines on 39 detection and 9 localization benchmarks while maintaining robustness against real-world perturbations and state-of-the-art generators like GPT-Image-2.
Don’t Click That: Teaching Web Agents to Resist Deceptive Interfaces
LLMs struggle with deceptive web interfaces. This paper introduces DUDE, a framework using hybrid-reward learning and experience summarization to teach web agents to resist clickbait and scam elements, reducing susceptibility by 53.8% while maintaining task completion rates.
Qwen-Scope: Turning Sparse Features into Development Tools for Large Language Models
Tackles LLM opacity by introducing Qwen-Scope, an open-source suite of sparse autoencoders (tools that decompose model thinking into interpretable features) across 14 SAE variants on Qwen models, enabling inference-time steering, evaluation analysis, multilingual safety classification, and fine-tuning optimization without modifying weights. Results show SAEs function as practical development interfaces beyond post-hoc analysis—controlling behavior, detecting benchmark redundancy, and mitigating code-switching and repetition in training.
SlimQwen: Exploring the Pruning and Distillation in Large MoE Model Pre-training
By comparing pruning pretrained models against training from scratch and progressive against one-shot pruning schedules, SlimQwen studies MoE compression at pretraining scale. The work finds pruning beats from-scratch training, expert merging converges after continued training, and progressive schedules beat one-shot compression, compressing Qwen3-Next-80A3B to 23A2B while retaining performance.
Tackles personalized user understanding by proposing UserGPT, which uses LLMs to generate coherent user personas from noisy behavioral histories through a pipeline combining a behavior simulation engine, semantic data transformation, and curriculum-driven training with reinforcement learning, achieving 73.25% accuracy on tag prediction and 75.28% on summary generation while compressing behavioral records by 98%.
Baidu
WebGameBench: Requirement-to-Application Evaluation for Coding Agents via Browser-Native Games
Coding agent evaluations grade code artifacts rather than delivered applications. WebGameBench instead requires agents to build browser-playable games from specifications and grades them via runtime interaction in actual browsers, revealing that while top agents achieve 76.9% playable delivery, only 20.2% fully satisfy requirements.
ByteDance
A-CODE: Fully Atomic Protein Co-Design with Unified Multimodal Diffusion
A-CODE designs proteins at the atomic level rather than at the level of protein building blocks, using a unified diffusion model that simultaneously predicts atom types and positions in one stage. It outperforms two-stage methods on unconditional generation, matches state-of-the-art binder design, and achieves 10× higher success on hard tasks while enabling non-canonical amino acid modeling for the first time.
Agentic Discovery of Exchange-Correlation Density Functionals
Designs exchange-correlation functionals in density functional theory through an agentic LLM system that iteratively proposes and evaluates functional improvements, discovering SAFS26-a, which outperforms the top baseline by ~9%. The work reveals the need for domain-expert constraints to prevent AI from exploiting unphysical shortcuts.
MegaScale-Omni: A Hyper-Scale, Workload-Resilient System for MultiModal LLM Training in Production
Improves multimodal LLM training under dynamic workloads via MegaScale-Omni, a system featuring decoupled parallelism strategies, unified encoder-LLM representations, and workload balancing. It achieves 1.27×–7.57× throughput gains at thousand-GPU scale.
Training Long-Context Vision-Language Models Effectively with Generalization Beyond 128K Context
Extends Qwen2.5-VL-7B from 32K to 128K context with only 5B tokens via MMProLong, which generalizes to 256K–512K tokens and diverse downstream tasks without retraining. A systematic study of data mixtures shows balanced sequence-length distributions and retrieval-heavy compositions outperform target-length-focused data for long-context vision-language model training.
Huawei
EnvFactory: Scaling Tool-Use Agents via Executable Environments Synthesis and Robust RL
EnvFactory autonomously synthesizes executable environments and natural multi-turn trajectories, addressing the shortage of realistic training environments and data for tool-use agents. Using 85 verified environments, it generates 2,575 training trajectories and improves Qwen models by up to +15% on BFCLv3 and +8.6% on MCP-Atlas.
iFlyTek
AttnRouter: Per-Category Attention Routing for Training-Free Image Editing on MMDiT
AttnRouter is a per-category routing table that selects the best editing operation for each image modification type, paired with KVInject, a simplified attention manipulation that injects source image features into noise tokens for training-free image editing on MMDiT. Ground-truth routing improves quality by 6.4%, with a zero-shot classifier recovering 98% of gains despite modest accuracy.
SenseTime
SenseNova-U1: Unifying Multimodal Understanding and Generation with NEO-unify Architecture
SenseNova-U1 is a unified architecture for vision-language models where both understanding and generation emerge from a single underlying process, addressing the fragmentation of these capabilities. Models match top-tier understanding-only VLMs on standard benchmarks while supporting image generation, text-rich synthesis, and vision-language-action tasks.
StepFun
Boosting Omni-Modal Language Models: Staged Post-Training with Visually Debiased Evaluation
Current omni-modal benchmarks overstate progress by allowing models to answer queries using only visual information; this paper introduces OmniClean, a visually debiased benchmark with 8,551 queries, and OmniBoost, a three-stage post-training method that enables a 3B model to match a 30B model’s performance through mixed bi-modal training, reinforcement learning, and self-distilled data.
Tencent
CL-bench Life: Can Language Models Learn from Real-Life Context?
Addresses the gap between lab benchmarks and real-world AI use via CL-bench Life, a human-curated benchmark of 405 messy, real-life contexts (group chats, personal archives, behavioral traces) with 5,348 verification rubrics. Even frontier models achieve only 19.3% task-solving rates, revealing that real-life context learning remains fundamentally unsolved.
OpenSearch-VL: An Open Recipe for Frontier Multimodal Search Agents
Releases OpenSearch-VL, a fully open recipe for multimodal deep search with curated training data, diverse tool environments (text/image search, OCR, image enhancement), and a fatal-aware RL algorithm that gracefully handles tool failures. The system achieves 10+ point improvements across seven benchmarks and matches proprietary models on several tasks.
Xiaomi
By integrating WorldRec (a reconstruction module using 3D scene queries for multi-view consistency) and WorldGen (a video generation module trained via bidirectional pretraining and causal fine-tuning), JWM addresses autonomous driving simulation. The joint system achieves improved consistency and fidelity for closed-loop simulation and synthetic data generation.
Technical AI Safety Publication Highlights
There were 172 AI-safety-related papers published by Chinese researchers this edition. Highlights are below; a full list with summaries is available here.
Agentic Safety
Safactory: A Scalable Agent Factory for Trustworthy Autonomous Intelligence
Safactory is an integrated framework that connects simulation, data management, and model improvement into a closed-loop system for agent development. It couples a parallel simulation environment (for generating agent trajectories), a data platform (for storing and extracting behavioral patterns), and an autonomous evolution system (for reinforcement learning and model distillation). The authors position this as infrastructure for systematic risk discovery and continuous safety improvement as models transition from conversational assistants to autonomous agents operating in real environments.
Institutional affiliations: Shanghai AI Laboratory
The Capability Paradox: How Smarter Auditors Make Multi-Agent Systems Less Secure
Semantic hijacking attacks exploit multi-agent LLM systems by embedding harmful requests in domain-specific narratives that Worker agents report to a Manager. Testing across 12 Manager models reveals a capability paradox: stronger Workers increase attack success from 18.4% to 63.9%, because they express adversarial conclusions with greater linguistic certainty, causing Managers to comply. Mediation analysis confirms certainty drives 74% of this effect. Heterogeneous ensemble verification—pairing Workers with asymmetric expertise—breaks this chain, reducing attacks to 2.0%.
Institutional affiliations: University of Chinese Academy of Sciences, Max Planck Institute for Security and Privacy, Henan Yinzhu Safety Technology Co., Harbin Institute of Technology
Alignment
Explaining and Breaking the Safety-Helpfulness Ceiling via Preference Dimensional Expansion
MORA (Multi-Objective Reward Assimilation) addresses the trade-off between helpfulness and safety in LLM alignment by rewriting prompts to unlock diverse reward dimensions rather than forcing compromises along a fixed frontier. The method identifies that prompts themselves constrain achievable multi-dimensional rewards, then expands diversity through pre-sampling and question rewriting to incorporate multiple intents. Experiments show 5–12.4% improvements in individual metrics (particularly harmlessness) after multi-objective alignment, with 4.6% average gains in simultaneous optimization.
Institutional affiliations: Huazhong University of Science and Technology, Nanyang Technological University, Tsinghua University, Chongqing University
Internalizing Safety Understanding in Large Reasoning Models via Verification
Safety Internal (SInternal) reframes alignment by training reasoning models to evaluate their own outputs for safety rather than merely detect unsafe inputs. The framework uses expert reasoning trajectories to teach models to critique their generated answers. Models trained this way show stronger generalization against jailbreaks and provide better initialization for reinforcement learning alignment, suggesting that internalized verification produces more robust safety than supervised imitation alone.
Institutional affiliations: University of Science and Technology of China, National University of Singapore, Shanghai Artificial Intelligence Laboratory
Evaluation and Benchmarks
IndustryBench: Probing the Industrial Knowledge Boundaries of LLMs
IndustryBench is a 2,049-item benchmark for industrial procurement QA grounded in Chinese national standards and product specifications. Unlike general LLM benchmarks, it explicitly separates raw correctness from safety violations—flagging when models introduce unsupported details that contradict safety clauses or regulatory thresholds. Across 17 models, the best achieves only 2.08 on a 0–3 scale; however, extended reasoning often worsens safety-adjusted scores by hallucinating safety-critical specifications. The benchmark demonstrates that leaderboard rankings collapse when safety compliance is properly weighted.
Institutional affiliations: Alibaba Group
Safe, or Simply Incapable? Rethinking Safety Evaluation for Phone-Use Agents
PhoneSafety is a benchmark of 700 safety-critical moments in real phone interactions that distinguishes between three outcomes: models taking safe actions, unsafe actions, or failing to act at all. Current evaluations conflate these—a model avoiding harm might reflect genuine safety judgment or mere incapability. Testing eight phone-use agents reveals that stronger general performance does not predict safer choices at risky moments, and that inability to act correlates with visual/operational difficulty rather than safety robustness.
Institutional affiliations: Tencent Hunyuan; The Chinese University of Hong Kong, Shenzhen; Tsinghua University
SkillSafetyBench: Evaluating Agent Safety under Skill-Facing Attack Surfaces
SkillSafetyBench evaluates a blind spot in agent safety: adversarial inputs embedded in task-relevant skill materials or local files can override benign user requests and trigger unsafe actions, even when the model itself is aligned. The benchmark includes 155 test cases across 47 tasks and 6 risk domains, showing that agents consistently fail when malicious content is injected into skills rather than user prompts. Findings highlight that safety depends on agent architecture—how it interprets skills, trusts context, and executes actions—not just model alignment alone.
Institutional affiliations: Shanghai AI Laboratory, Peking University, East China Normal University
Governance and Policy
Not All Anquan Is the Same: A Terminological Proposal for Chinese Computer Science and Engineering
This paper argues for disambiguating “anquan” in Chinese technical writing by adopting “anbao”(安保)for security and reserving “anquan”(安全)for safety. The single word currently conflates non-adversarial failures (safety) with intentional attacks (security), creating conceptual confusion in standards interpretation, risk analysis, and cross-disciplinary work. The author demonstrates how this conflation undermines precision in functional safety, automotive systems, cybersecurity, and AI governance, and proposes dual-track terminology practices to enable clearer scientific argumentation and assurance claims.
Institutional affiliations: Wuhan University
Guardrails and Deployment Safety
ML-Bench&Guard constructs a multilingual safety benchmark directly from regional legal texts rather than translated taxonomies, covering 14 languages with jurisdiction-specific risk categories. ML-Guard, a diffusion-based guardrail model, provides policy-conditioned compliance assessment—outputting safe/unsafe verdicts (1.5B variant) or detailed explanations aligned to local regulations (7B variant). The approach addresses a concrete deployment challenge: existing multilingual safety systems rely on generic risk categories that don’t map to region-specific legal requirements, potentially creating compliance gaps in cross-border LLM deployment.
Institutional affiliations: University of Illinois Urbana-Champaign, Fudan University, University of Chicago
Interpretability
Decomposing and Steering Functional Metacognition in Large Language Models
Residual stream analysis reveals that LLMs encode decomposable functional metacognitive states—internal variables tracking evaluation awareness, self-assessed capability, perceived risk, and effort allocation—that are linearly decodable from model activations. By steering activations along probe-derived directions, researchers demonstrate each state causally modulates reasoning behavior in distinct ways, affecting verbosity, accuracy, and safety responses. This mechanism suggests benchmark performance conflates task competence with activation of specific internal states, raising questions about what standard evaluations actually measure.
Institutional affiliations: Shopee
This paper identifies Refusal-Escape Directions (RED): continuous input perturbations that shift aligned models from refusing harmful requests to answering them while preserving semantic understanding of the harm. The authors decompose RED mathematically across model components, pinpointing normalization layers, residual connections, and output modules as structural sources of jailbreak vulnerability. They demonstrate a safety-utility trade-off: eliminating RED requires shared modules (attention, MLP) to suppress refusal-escape paths without breaking benign capabilities, revealing why aligned models remain jailbreakable despite training.
Institutional affiliations: Chinese Academy of Sciences, University of Chinese Academy of Sciences
Robustness and Adversarial Attacks
Misrouter: Exploiting Routing Mechanisms for Input-Only Attacks on Mixture-of-Experts LLMs
Misrouter exploits MoE routing mechanisms through input-only attacks—adversarial queries that manipulate which experts process tokens without direct model access. The method identifies weakly aligned experts and steers routing toward them while away from safety-trained ones, then optimizes prompts to trigger unsafe outputs while maintaining routing stability. Attacks transfer from open-source surrogate models to commercial API services, suggesting MoE’s routing layer presents an exploitable vulnerability in production systems.
Institutional affiliations: Nankai University, Nanyang Technological University
Model-Agnostic Lifelong LLM Safety via Externalized Attack-Defense Co-Evolution
EvoSafety decouples red-teaming and defense into externalized, reusable structures rather than embedding them in model weights. Attack discovery uses a skill library that expands beyond saturation, while defenses run as lightweight auxiliary models with memory retrieval, transferable across victim LLMs without retraining. The framework achieves 99.61% defense success in filter mode with fewer parameters than existing guardrails, and supports both steering intrinsic model defenses and direct input filtering.
Institutional affiliations: City University of Hong Kong, Beijing University of Posts and Telecommunications, Wuhan University, Beihang University, Beijing Academy of Artificial Intelligence
On the Horizon
There’s still limited information on the bilateral AI Track 1 dialogue—we’ll bring details as they come.
For more on how we select and track content, see our methodology here.
The China AI Bulletin is maintained by the Safe AI Forum (SAIF), a US 501(c)3 facilitating international cooperation on extreme AI risks. Views expressed represent individual authors’ perspectives, not official SAIF positions.
S&T Daily is the official paper of the Ministry of Science and Technology (MOST).
《智能体规范应用与创新发展实施意见》
安全可控
创新驱动/应用牵引
夯实发展基础
守牢安全底线
强化应用牵引
建设创新生态
智能体注册平台
2026年以来,OpenClaw广泛应用 … 暴露出智能体在指令诱导下可发起网络攻击等风险隐患
地方实际
加快推进人工智能... 综合性立法
原则性、参考性技术文件
“Dominance” in the sense of “control”: 人类主导权影响
防范人工智能脱离人类监督或威胁人类生存发展
重点评估其失控风险以及其对产业和社会的影响
可信应用、防范失控
人工智能安全标准体系
智能体应用安全基本要求
特朗普总统访华期间,两国元首就人工智能问题进行了建设性交流,同意开展人工智能政府间对话。