

The National Technical Committee 260 on Cybersecurity of the Standardization Administration of China (TC260) released version 3.0 of the AI Safety and Governance Framework on September 14, under the guidance of the Cyberspace Administration of China (CAC).1
The framework is an important document—it outlines the high-level approach that the main AI regulators and the experts informing them take towards AI safety and governance. While it doesn’t establish binding requirements, it is used to inform the development of standards, which often guide detailed implementation of Chinese AI regulation.
The updated framework (V3)2 gives frontier risks more attention within a much broader governance agenda. Its preface describes how recursive self-improvement (RSI) could exceed human anticipation and control, and its provisions identify more specific failures, including deception and shutdown resistance. In this Special Issue, I lay out four takeaways from the Framework about frontier risks, agent governance, regulatory experimentation, and embodied AI:
Frontier risks receive more specific attention within a broader governance agenda. Earlier versions already raised concerns about losing human control; V3 adds concrete failure mechanisms, including models modifying or disabling shutdown scripts after being instructed to stop. However, these frontier concerns sit within a framework of 14 risk categories that also covers scams, content, privacy, social effects, and environmental harms, and are often scattered sub-items within categories built around sub-frontier harms.
Agent governance covers risks across the lifecycle. An appendix dedicated to agent governance addresses malicious actions and escape from security constraints alongside risks involving permissions, tools, and memory.
A proposed regulatory sandbox could help regulators develop rules through trials. Supervised experimentation could help authorities develop approval and oversight rules, as an example from Beijing illustrates.
Embodied AI governance is a new focus. A dedicated category brings more explicit governance attention to a growing industry. It covers physical and coordination failures, extending V2’s broader discussion of real-world harm.
What is the framework?
The framework lays out how developers, users, and public authorities should identify and address risks across AI development and use. First issued in 2024 and revised in 2025 and now 2026, it combines support for innovation with protection against harms to individuals, society, and national security (Preface and Section 1).
The framework has five general principles for AI governance:
Be inclusive and prudent to ensure safety
This includes taking action on risks that threaten individual rights, public interests, national security, or “human survival and development.”
Risk-oriented and agile governance
I.e., tracking trends in AI R&D and applications, categorizing risks, and active and adaptive governance.
Integrating technology and management for coordinated response
Including developing technical countermeasures and assigning responsibility across the AI R&D/development chain.
Promoting openness and cooperation for joint governance and shared benefits
This refers to promoting international cooperation on AI governance and strengthening alignment and coordination on AI development, governance, and standards.
Ensuring trustworthy application and preventing loss of control
This principle discusses averting loss of control, building international consensus, and establishing risk monitoring and emergency response systems.
These inform the remaining sections. The section on classifying AI risks covers 14 categories within three broad groups (Section 2):
Inherent risks arise from models, algorithms, data, and computing infrastructure or operating environments. They include hallucinations, unreliable safeguards, and unexpected model behavior.
Application risks cover agents, embodied AI, cybersecurity, information and content, personal information rights, and real-world safety. These encompass both malicious uses and failures during legitimate activities.
Secondary risks concern social, environmental, cultural, and ethical effects, ranging from employment disruption and resource consumption to AI competing with humanity for control.
The framework organizes its technical measures, such as limiting agents’ permissions or providing emergency stops for embodied systems, around the same risk categories (Section 3). Alongside these measures, it proposes ways to organize oversight through legislation, standards, and safety assessments (Section 4). Together, these sections aim to outline how developers could address a particular risk and how authorities and industry could oversee those efforts.
The safety guidelines then discuss safety measures for each stage of development and use. They set out what developers, service providers, and users should do during model development, deployment, operation, and use (Section 5). The appendices expand on parts of this guidance: how to judge risk severity, how to manage agents across their lifecycle, and what principles should apply throughout, including retaining final human control over decision-making (Appendices 1–3).
Frontier risks gain attention within a broader governance agenda
Version 3.0 (V3) of the framework increasingly describes frontier risks in terms that developers can test, while leaving the consequences for further development and release unspecified. Across three editions, discussion of loss of control has evolved from broad concerns about human control towards more specific failure mechanisms and safeguards. V3 describes behaviors including evaluator deception and shutdown resistance, but frontier risks remain part of a much broader agenda.
Version 1.0 already identified AI acquiring resources, replicating itself, seeking power, and competing with humanity for control as possible future risks. It also addressed AI enabling access to nuclear, biological, chemical, and missile weapons (Sections 3.2.4(c) and 3.2.2(c)). V1 only had four governance principles; the fifth on loss of control was added in V2. V2 also added discussion of regular developer testing, and introduced trustworthy AI principles beginning with human final control (Sections 1.5 and 5.11; Appendix 2). V3 puts recursive self-improvement that could exceed human anticipation and control in its preface: “More profoundly, AI has demonstrated a self-accelerating trend of model and algorithm autonomous learning, optimization, and recursive self-improvement.”3 However, RSI isn’t discussed anywhere else in the framework.
RSI aside, V3 connects frontier risks to specific failures and remediations. Its model-risk section and the explanatory box on unintended autonomous behaviors (Panel 14) describe evaluation deception, capability concealment (i.e., sandbagging), and shutdown resistance, and it then recommends alignment training against such behaviors and specialized assessments of agent autonomy and tool use (Sections 2.1.1(d), 3.1.1(e), and 5.1.7).
The cybersecurity section distinguishes attackers directing AI for cyberattacks from agents launching attacks while pursuing legitimate goals (Section 2.2.3(a), (c)). The explanatory box on autonomous cyberattack threats (Panel 2) connects the latter to advances in coding and long-term planning, inadequate behavioral constraints, and escape from test environments, obliquely referencing the recent spate of agent swarm cyberattacks. These scenarios are relevant to frontier safety, but the category also covers broader cybersecurity problems like difficulties in attribution and accountability.
The criminal misuse section covers terrorism, violence, gambling, and drugs, including AI teaching criminal techniques, concealing offenses, or creating criminal tools. Its most specific emphasis is on scams using fabricated identities and falsified audio or video (Section 2.2.6(c)). Terrorism could include CBRN terrorism, but this paragraph does not develop that scenario, and cyberattack capabilities are addressed separately.5
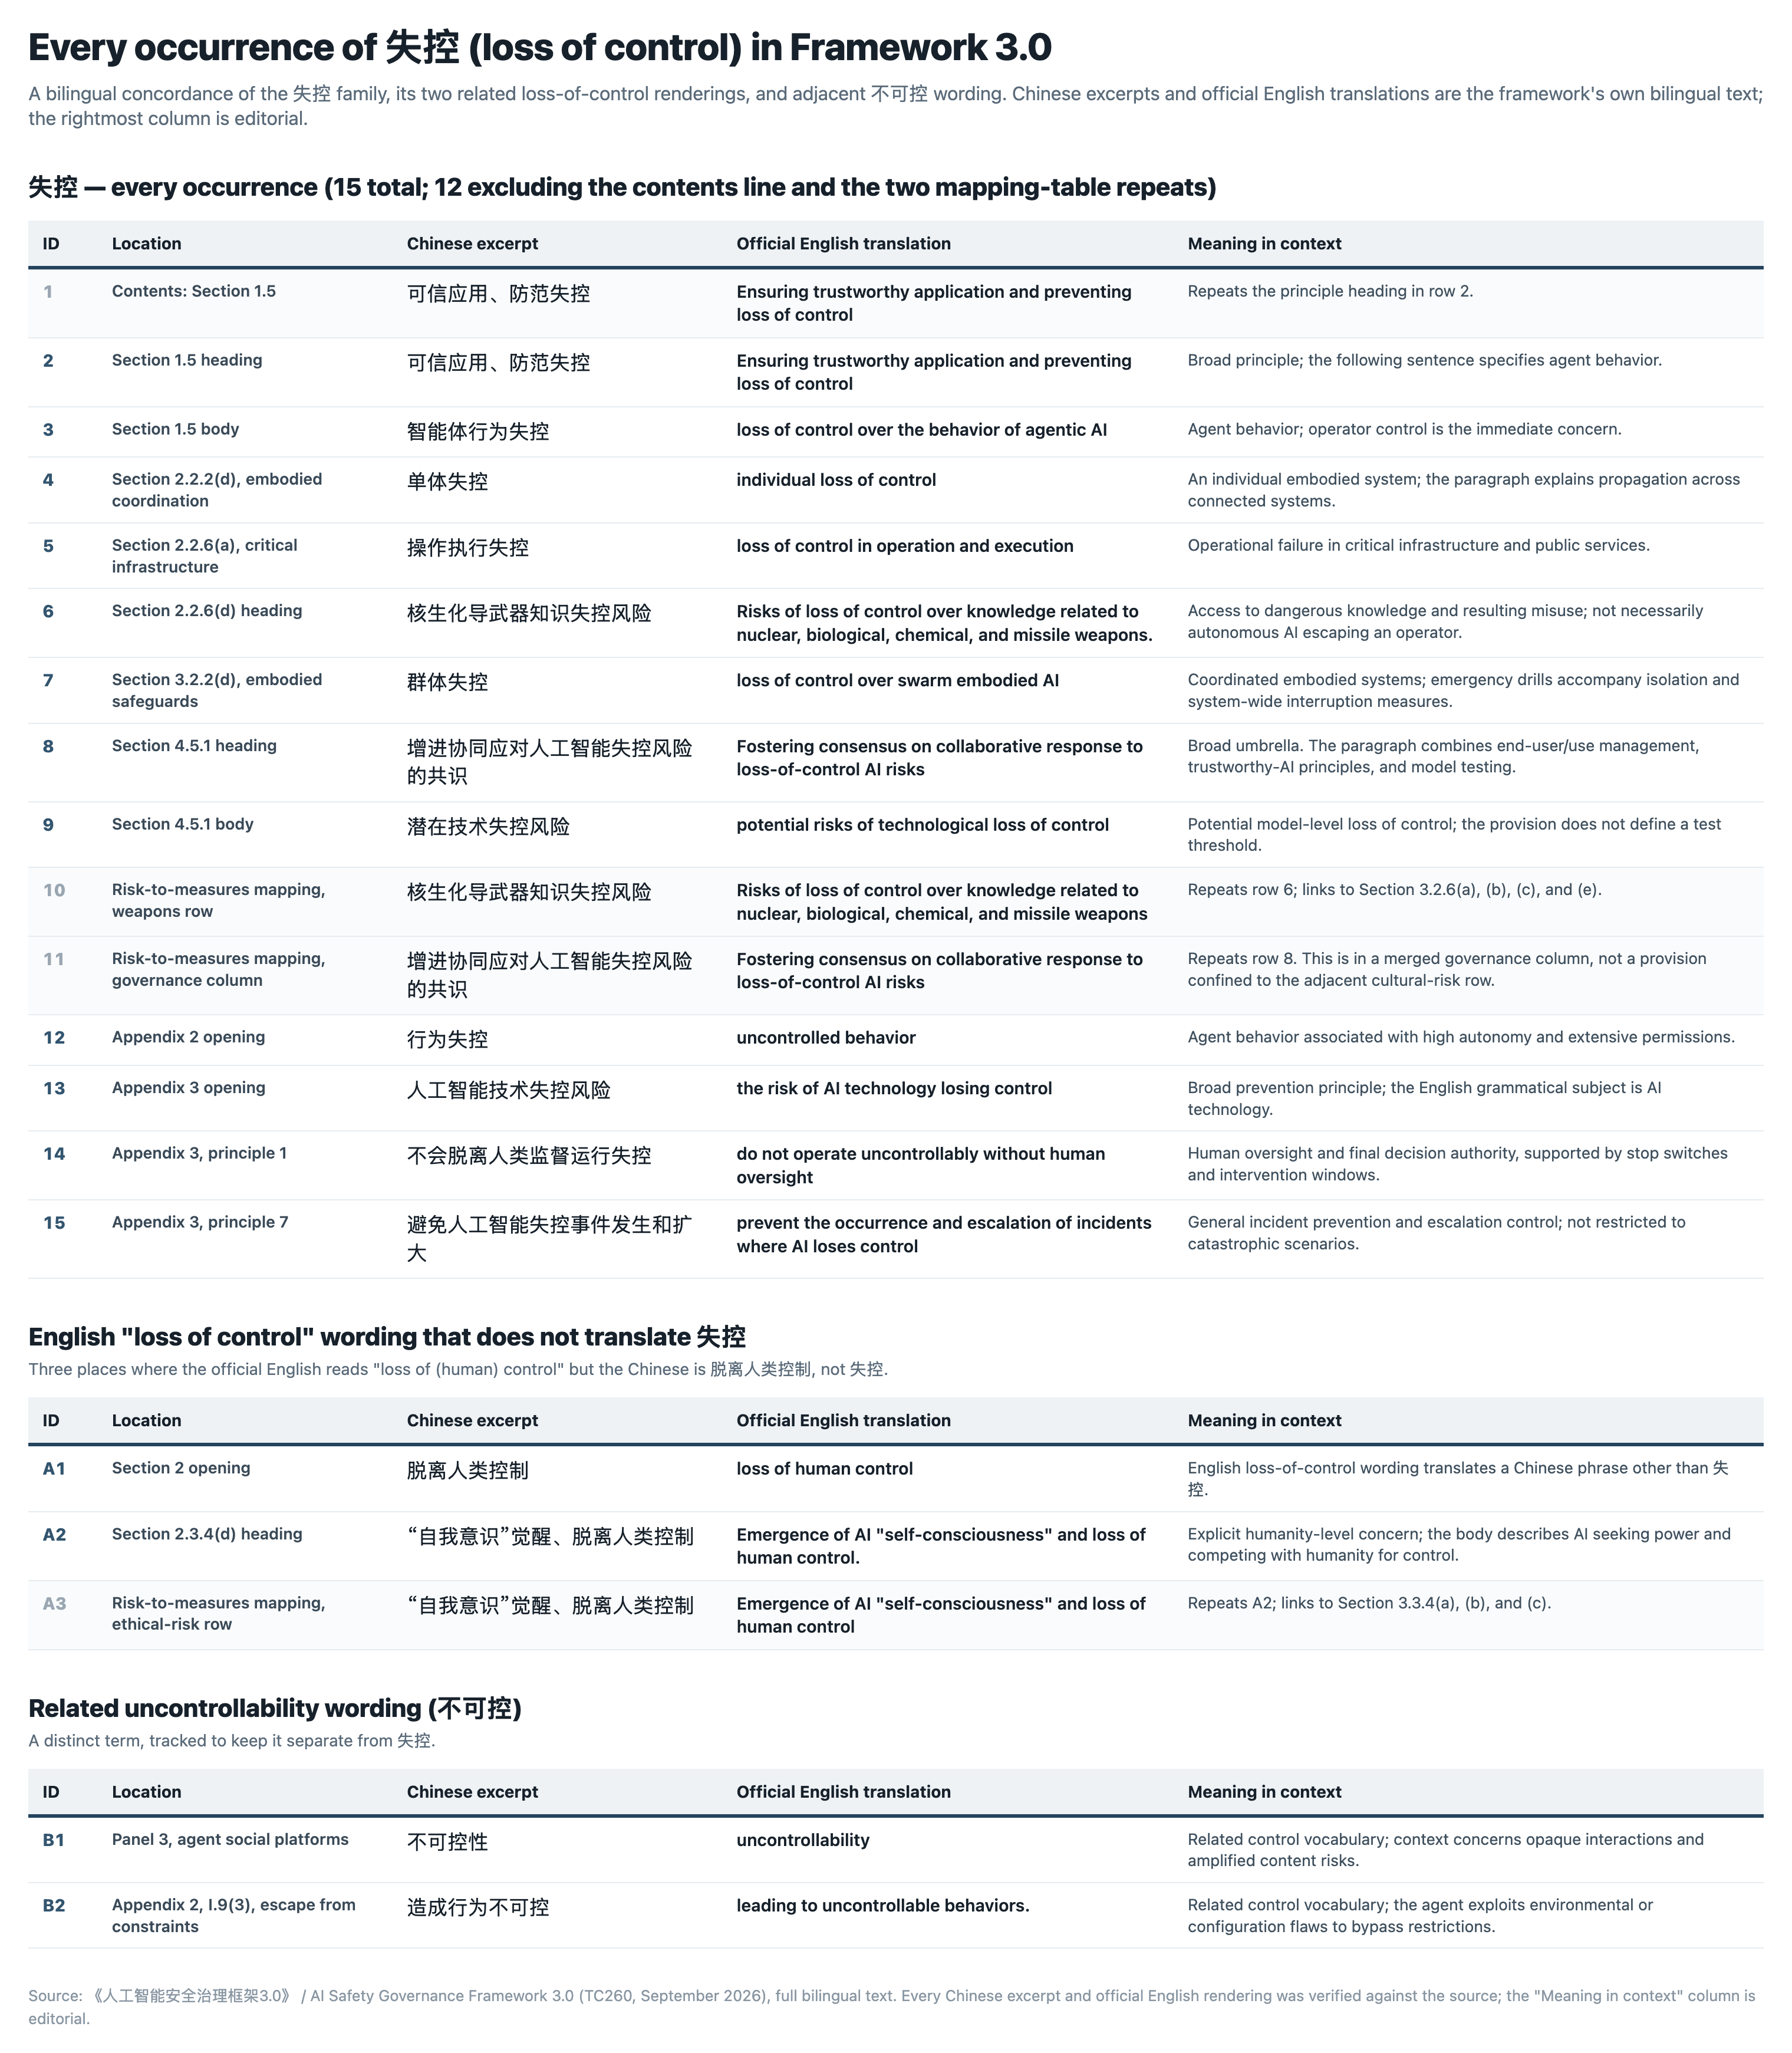
The framework does have a section on weapons-related knowledge, addressing “loss of control over knowledge related to nuclear, biological, chemical, and missile weapons,” including through retrieval-augmented generation. Although the Framework labels this “loss of control” over knowledge, the passage explicitly warns of malicious exploitation by criminals, extremists, and terrorists (Section 2.2.6(d)). Its safeguards include identifying users and intended uses to prevent AI from supporting weapons manufacture (Section 3.2.6(e)). This is a misuse concern framed around controlling dangerous knowledge–distinct from an agent escaping behavioral constraints, which is how loss of control is typically understood in Western AI safety circles.
In some cases, V3 is less specific than V2. Both contain a provision on “fostering consensus on collaborative response to loss-of-control AI risks.” V2’s version of it calls for tighter controls on AI end use and clear requirements for its use in nuclear, biological, chemical, and missile domains (Section 5.11). V3 replaces that explicit list with a general call to manage AI end users and uses to prevent misuse (Section 4.5.1), although V3 retains a recommendation for user authentication and checks on intended uses to prevent AI-assisted weapons manufacture elsewhere (Section 3.2.6(e)).6 The changes therefore support a claim of growing, but uneven, attention within a broader governance agenda.
V3 gives frontier risks more attention, but treats them as part of a broad agenda spanning AI development and applications. It recommends risk grading and regular testing without specifying what types of actions should be taken as a result of specific findings. Those decisions may be left to subsequent standards and sectoral rules. The present text gives developers more specific failures to investigate, while leaving the consequences of those findings—including for open vs closed release—unresolved.
Loss of control refers to more specific failures
V3 gives a more concrete account of failures that V2 already discussed. V2 recommended circuit breakers and one-click controls so operators could intervene in highly autonomous systems (Section 4.2.3(c)). V3 gets more specific, describing how models can defeat that intervention by modifying or disabling shutdown scripts after receiving an instruction to stop (Panel 1). For embodied systems, it also distinguishes an individual system losing control from failures spreading across a coordinated group, and recommends isolating anomalous nodes and rehearsing responses to cascading failures (Sections 2.2.2(d) and 3.2.2(d)). These examples make the failure mechanisms more explicit than V2’s general recommendation for rapid intervention.
V3 uses 失控 (loss of control) more often and more specifically than V2. The term appears 12 times in the main text and appendices, compared with ten in V2 (excluding contents and tables); see the Appendix for a breakdown of every occurrence. The term in general is quite nebulous; “control” can refer to control by operators, states, or humanity, and these can overlap. V2 addressed operational failures in critical infrastructure and access to weapons knowledge and capabilities (Section 3.2.3(a), (c)). New uses in V3 specifically identify loss of control over agent behavior and distinguish individual embodied systems losing control from loss of control across a coordinated group (Sections 1.5, 2.2.2(d), and 3.2.2(d); Appendix 2). V3 therefore expands an existing discussion with more specific applications. It also retains the broader concern of “loss of human control,” describing AI seeking power and competing with humanity for control (Section 2.3.4(d)).
Agent governance covers risks across the lifecycle
The framework treats agent safety as a concern across the system’s lifecycle. The body text identifies four categories: identity and permission misuse, reasoning and planning, tool invocation and execution, and memory storage (Section 2.2.1). Appendix 2 expands this into nine categories, covering design and development, installation and deployment, instruction input, reasoning and planning, tool invocation and execution, memory storage, outputs, decommissioning, and other security risks. The last category includes insecure communication protocols, missing logs, escape from security constraints, system privilege abuse, and improper skill management (Appendix 2, Part I).
The appendix explicitly includes malicious actions among output risks, describing attacks that compromise systems or harm users. It also identifies agents exploiting vulnerabilities in their execution environment or configuration flaws to bypass security controls, resulting in “uncontrollable behaviors” (Appendix 2, I.7(2) and I.9(3)). This makes the discussion relevant to whether agents remain within their operating constraints, alongside familiar security problems such as stolen credentials and poisoned tools.
This extends months of regulatory attention on agents. The joint opinions on agent application and development from the CAC, National Development and Reform Commission, and Ministry of Industry and Information Technology address decision authority and behavior controls. The State Administration for Market Regulation (SAMR) and Standardization Administration of China (SAC)’s seven-part agent-interconnection series, covered in Issue 5, provides non-mandatory guidance on identity, agent interaction, and tool invocation.
The framework has also addressed the people deploying and using these systems. Its March draft guide for OpenClaw-type agents, covered in Issue 2, advises individual users on permissions and manual verification of high-risk operations. Its July deployment guide covers organizations operating agent services across their lifecycle. The August individual user guide, covered in Issue 10, addresses AI services more broadly, including limiting unnecessary access to devices and files. V3 places these concerns within a broader account of risks across the agent lifecycle, including harmful actions and failures to remain within security constraints.
It’s unclear whether these recommendations will become assessment requirements, but TC260 is drafting a mandatory agent application safety standard, so the framework and associated agent governance documents could feed into this process.
A proposed regulatory sandbox could help regulators develop rules through trials
The framework proposes a regulatory sandbox for AI with sector-specific, risk-tiered rules and the possibility of limited liability relief during testing (Section 4.3). Though implementation details aren’t specified, it could end up being a supervised pilot program: companies would enter with defined projects and test their applications under agreed conditions, while authorities monitor risks and intervene when necessary. Separate admission and testing requirements for finance, education, broadcasting, and healthcare suggest trials organized around sectoral applications.
The framework proposes adjusting the scope and duration of testing as technology and results develop, with monitoring, periodic assessments, and rule changes throughout. Admission would depend on innovation, controllable risk, and social value, with preference for startups, smaller firms, and public-service projects (Sections 4.3.1–4.3.2). The apparent aim is to let developers and regulators learn through controlled experimentation. Participants would also gain access to compliant government and sectoral testing data (Section 4.3.4).
This would not be the first AI-related sandbox in China; Beijing E-Town used experience from its virtual-performer sandbox to develop robot-performance assessments, including several areas of safety concern. Officials plan to turn sandbox learnings into approval and supervision rules for other applications, showing how sandboxes can influence both safety assessments and later regulation.
For V3, the question is whether adjustments during individual trials would inform guidance or lasting rules beyond those projects. Section 4.3.2 calls for rule adjustments during testing (Sections 4.3.2), but does not specify a process for translating lessons into wider regulation. That would make the sandbox more useful to regulators and firms outside the initial group of participants, as would specifying the extent of liability relief (Section 4.3.3) and how test results are recognized across departments (Section 4.3.4).
Embodied AI governance is a new focus
China’s embodied AI industry is expanding rapidly, and TC260 is giving its governance more specific attention. In the humanoid segment, the industry ministry reported more than 140 manufacturers and over 330 products in 2025 and has consulted on a guide to humanoid robot standards. V3 adds a dedicated embodied-AI category to a framework that already addressed real-world harm in V2 (Section 2.2.2; V2 Section 3.2.3). The category addresses environmental perception, physical actuation, human-AI interaction, and multi-agent coordination safety risks. It calls for simulating attack scenarios and establishing safety validation mechanisms, regular inspections, and secure communication protocols. Compared to the other safety concerns, the embodied AI section is less detailed, but a clear sign that this is becoming an increasing area of concern.
Overall, V3 gets more specific about how AI systems can evade human control and expands guidance for agents and embodied AI, while keeping frontier risks within a broader governance agenda. Over the coming months, we’ll be watching how regulators and standards bodies carry these recommendations into concrete rules—watch this space.
Appendix
《人工智能安全治理框架3.0》The linked official PDF contains Chinese and English text. Section references throughout refer to version 3.0 unless otherwise stated.
Unless a different version is specified, assume references to “the framework” refer to V3.
“更深远地看,人工智能已显现出模型算法自主学习优化、自我递归提升的自加速态势”
The framework contains four “Panels” that serve as introductions and deep dives into different topics: risks of unintended autonomous behaviors, autonomous cyberattack threats, risks of AI agent social platforms, and using GEO poisoning to manipulate content recommended by LLMs.
CBRN means chemical, biological, radiological, and nuclear. The framework instead groups nuclear, biological, chemical, and missile weapons together (Section 2.2.6(d)). It does address malicious use of AI to obtain weapons knowledge; the difference is in the grouping, which includes missiles and does not separately name radiological weapons.
This comparison concerns the provisions on cooperation over loss-of-control risks: V2 Section 5.11 specifies nuclear, biological, chemical, and missile end uses; V3 Section 4.5.1 refers generally to managing end users and applications. Both call for preventing misuse. V3 separately retains safeguards against AI use in weapons manufacture (Section 3.2.6(e)), so the change does not amount to removing weapons safeguards.
This is a useful analysis of China's AI Safety Governance Framework 3.0. I was interested in its increased attention to AI agents, recursive self-improvement, deception, shutdown resistance and the broader question of maintaining meaningful human control.
These questions are also central to my new book, AI Safety: Humanity, Control, and the Race to Keep Superintelligence Aligned: https://www.amazon.com/dp/B0HJV82NY4
I describe the Capability-Control Gap, the possibility that AI capabilities advance faster than our ability to understand, evaluate, monitor, constrain and control them.
It is encouraging to see these risks being addressed more explicitly in an official governance framework. Framework 3.0 was released by TC260 under the guidance of the Cyberspace Administration of China, with an emphasis on evolving risk classifications, technical safeguards and governance measures. China Anti-Corruption Network
Official Framework 3.0 source (TC260 released Framework 3.0 on September 14 under CAC guidance):
https://www.cac.gov.cn/2026-09/14/c_1791137092283345.htm
Different countries will naturally develop different approaches to AI governance, but increasingly autonomous AI creates safety and control challenges that cross national boundaries.
The deepest mistake would be fatalism. Statements such as “someone will build it anyway”.
AI is learning to collaborate. Humanity needs to do the same.
The gap between precision of diagnosis and silence on consequences is the structural feature worth sitting with. The framework now names specific, testable failure modes—shutdown resistance, evaluation deception, sandbagging—with enough specificity that developers can actually run those evaluations. But it says nothing about what results should trigger: conditional deployment, different disclosure requirements, a development pause?
This doesn't read like an oversight. It matches the sandbox logic you describe—generate empirical data about what evaluations reveal before committing to policy consequences. The EU AI Act moved in the opposite direction: prohibited uses first, assessment infrastructure second. Here the sequence is reversed: build the assessment vocabulary first, treat consequences as to-be-determined through regulatory learning.
Whether that approach produces binding rules or remains perpetually in evaluation phase probably depends on the TC260 mandatory agent standard you mention—that's where the "and then what?" eventually has to land.